
Peptide discovery is entering an era of abundance. Researchers can build larger libraries, incorporate noncanonical residues, constrain backbones in multiple ways, and use increasingly capable computational tools to propose or rank candidates. Yet many programs still organize discovery around a narrow objective: identify the strongest binder.
Affinity is important, but it is not a drug profile. A peptide must also be selective, soluble, synthetically tractable, sufficiently stable, and able to reach the relevant biological compartment. Depending on the program, it may need to cross a membrane, remain extracellular, internalize into a specific cell type, or sustain activity after transient exposure. A screen that reports only binding leaves these questions for later, when changing molecular direction is more expensive.
The next advance will not come from choosing experimental screening over computation, or computation over screening. It will come from designing experiments so that each round produces a more informative map of the chemical and biological landscape.
Library is already part of the hypothesis
A peptide library is never truly unbiased. Its length distribution, residue alphabet, cyclization chemistry, topology, display format, and synthesis method determine which molecules can be produced and which conformations can be explored. These choices also influence stability, solubility, permeability, and presentation of binding groups.
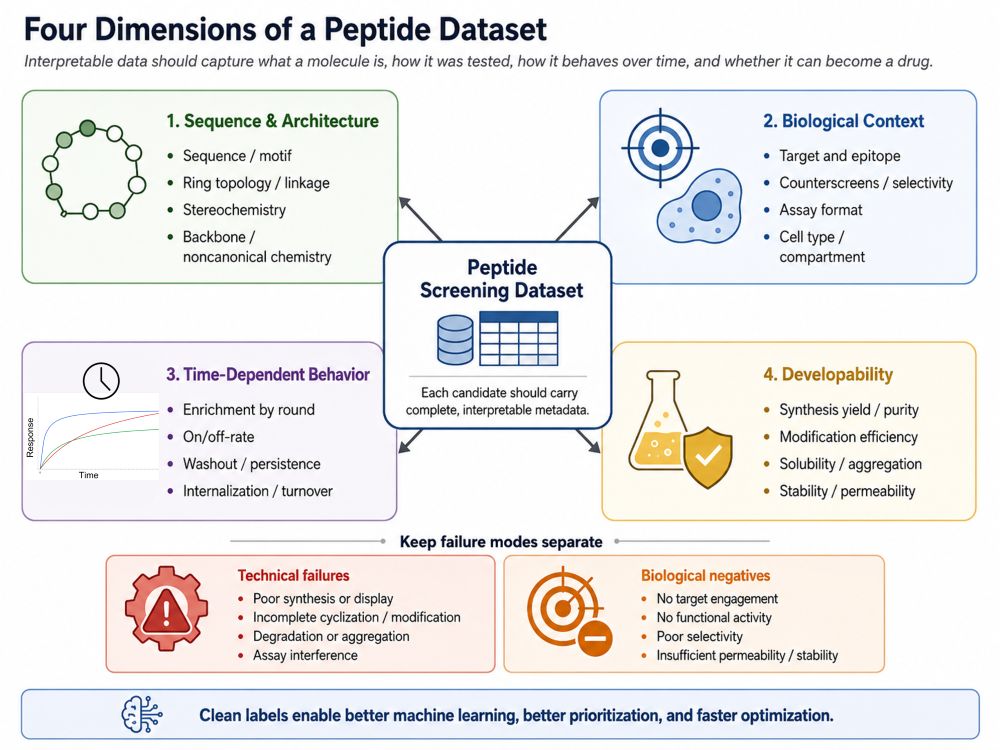
Peptide function is not encoded by sequence alone. Two molecules with similar residue composition can behave differently when one is linear and the other is cyclic, when stereochemistry changes, or when a backbone amide is modified. For constrained peptides, linkage position and ring topology can reorganize the conformational ensemble. A sequence-only analysis may therefore group together molecules that are chemically and pharmacologically distinct.
Recent work illustrates the opportunity. A 2026 study screened 15,360 fully random, sub-kilodalton cyclic peptides and identified a starting point against the intracellular Keap1–Nrf2 protein–protein interaction. Iterative design, synthesis, and testing produced a membrane-permeable inhibitor active in living cells. The broader lesson is that binding and permeability can be treated as connected design problems rather than sequential hurdles.
Screen in biological space, not only against a target
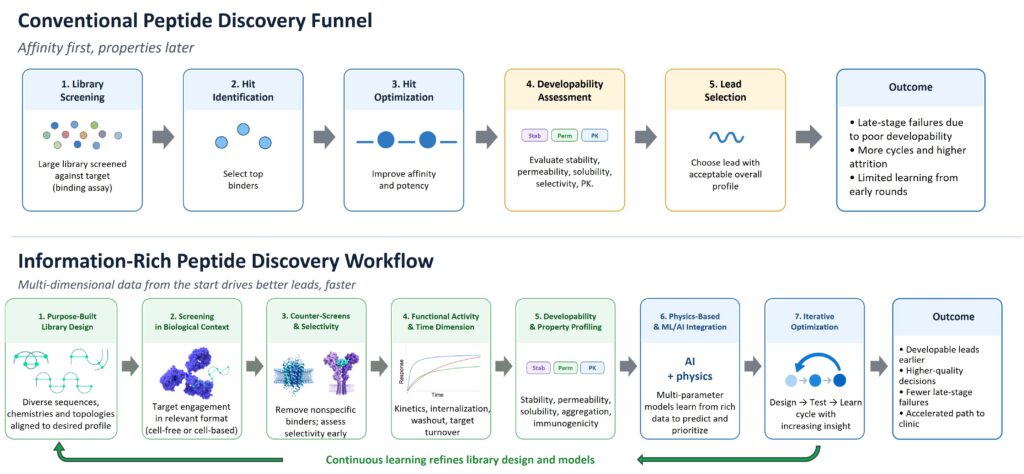
Purified-protein screens remain useful, particularly when material is limited or throughput is essential. But the assay format can become an unintended selection pressure. Peptides may recognize a purification tag, a surface, an exposed hydrophobic patch, or a conformation poorly represented in the native setting. High apparent affinity can also reflect nonspecific interactions that disappear in another assay.
The solution is not to force every primary screen into a complex cellular system. It is to design a staged assay hierarchy before screening begins. Early counterselections can remove binders to tags, matrices, related proteins, or abundant off-targets. Competition experiments can test dependence on the intended epitope. Homolog counterscreens can reveal selectivity within a target family.
Orthogonal confirmation through kinetic binding, solution-phase competition, biochemical function, or cell-based activity can distinguish reproducible target engagement from assay-specific behavior.
For intracellular programs, permeability and functional activity should enter the workflow as soon as candidate numbers permit. For extracellular targets, serum stability, target turnover, tissue context, and the consequences of sustained versus transient engagement may matter more. The objective is not to measure every property immediately, but to ensure that the screening cascade reflects where the molecule must ultimately work.
Most screening readouts are snapshots. Biology is not. An endpoint measurement can obscure differences in association rate, dissociation rate, target rebinding, internalization, degradation, or intracellular retention. A peptide with modest equilibrium affinity but a slow off-rate may produce stronger functional activity than a tighter binder that dissociates rapidly. Conversely, prolonged engagement may be undesirable when an off-target interaction creates risk.
Time can be incorporated in practical ways. Selection pressure can be increased by extending wash periods or adding soluble competitor. Candidates can be tested after defined exposure to serum, proteases, reducing conditions, or relevant tissue fluids. Cellular assays can separate immediate pathway modulation from activity that persists after washout. Internalization and cytosolic access can be measured at multiple time points rather than inferred from one image.
Round-by-round enrichment also contains temporal information. A sequence that rises steadily may be more credible than one that appears abruptly after a bottleneck. Intermediate sequencing data can reveal early enrichment, late artifacts, and architecture families that respond differently as selection pressure changes.
Preserve the reasons molecules fail
The final hit list is often the least informative version of a screening dataset. It contains the winners but discards much of the evidence needed to understand why they won.
For peptide programs, “inactive” is not a single label. A candidate may fail because it was not produced efficiently, did not display correctly, was not cyclized or otherwise modified, aggregated, degraded, bound nonspecifically, failed to enter cells, or reached the target without changing function. These outcomes should not be collapsed into one negative class. A model trained on them would be asked to learn biology from a mixture of technical and pharmacological failures.
Useful datasets require provenance. Starting-library abundance, enrichment by round, control behavior, counterscreen results, synthesis yield, purity, modification efficiency, assay conditions, batch identity, and detection limits should travel with each sequence. Missing values also need interpretation. “Not detected” can mean below an assay threshold, absent from the starting population, lost during processing, or simply not tested.
Physics-based modeling and machine learning are often presented as competing approaches. In peptide discovery, they are more useful when assigned complementary roles.
Physics-based calculations can examine conformational ensembles, intramolecular hydrogen bonding, solvent exposure, target contacts, and the consequences of a specific substitution. They are especially valuable when experimental data are sparse or a mechanistic explanation is needed. Their limitations include computational cost, sampling challenges, and sensitivity to the underlying model.
Machine learning can recognize relationships across larger datasets, rank candidates, propose combinations a human team might not prioritize, and support multi-parameter optimization. Recent work has coupled generative models with Bayesian optimization and prospective synthesis and testing to improve peptide scaffolds under experimentally defined constraints. Deep-learning methods are also becoming more capable of cyclic-peptide structure prediction and redesign, although limited training data remain a central challenge.
The most productive workflow uses physical insight to define plausible chemical space, experimental data to anchor predictions, and machine learning to identify the next informative measurements. Optimization should not collapse every objective into one opaque score. Teams should examine trade-offs directly: a modest loss in affinity may be acceptable if it produces a major gain in selectivity, stability, permeability, or manufacturability.
Build the learning strategy before the first hit
An integrated peptide campaign can be organized around five decisions. First, define the intended product profile early. Target compartment, route of administration, dosing expectations, selectivity requirements, and minimum functional effect should shape the screen.
Second, make molecular architecture an explicit variable. Sequence diversity matters, but diversity of constraint, stereochemistry, backbone composition, and topology may reveal different solutions to the same target.
Third, establish the assay hierarchy and controls in advance. Primary enrichment, counterscreens, orthogonal binding, functional activity, and developability measurements should answer distinct questions rather than repeatedly measure the same one.
Fourth, retain complete and interpretable data, including technical failures and uncertain outcomes. Computational methods cannot repair labels that confound failed production with failed biology.
Finally, test models prospectively. A model that explains an existing dataset may still fail on new architecture classes or assay conditions. The meaningful test is whether it selects the next peptides better than established heuristics—and whether those results improve the following round.
The output of a peptide screen should not be viewed only as a ranked list. It should be a calibrated map showing which sequences and architectures succeed under which conditions—and where uncertainty remains.
That map can reveal whether a target favors a particular topology, whether a stability gain repeatedly costs function, whether a permeability strategy generalizes, and which measurements best predict cellular activity. It can also prevent teams from optimizing an impressive binder that was never compatible with the intended medicine.
Peptide discovery will continue to benefit from larger libraries and more capable algorithms. But scale alone does not guarantee learning. The programs that move most efficiently will treat library design, screening, functional biology, physics, and machine learning as parts of one experimental system—built not merely to find a winner, but to understand how to make the next molecule better.
Karsten Eastman, PhD, is the CEO and co-founder of Sethera Therapeutics.